EEE undergraduate · NTU Singapore

Nguyen Quang Trung

Interested in multimodal LLMs — currently most excited about RL for reasoning and alignment.

I'm an Electrical & Electronic Engineering undergraduate at Nanyang Technological University, Singapore. I'm interested in multimodal LLMs, and lately most excited about reinforcement learning — for reasoning and for alignment.

I work as a research assistant at A*STAR and an undergraduate researcher at S-Lab, NTU. I'm really fortunate and grateful to work with and learn from Prof. Ziwei Liu, and to be mentored by Dr. Bo Li, Kaichen Zhang, Yuhao Dong, and Dr. Sun Shuo.

Most of this I taught myself — books and courses like CS285 for RL, Nathan Lambert's RLHF Book, implementations from Umar Jamil's channel — then sharpened through my mentors' advice and real projects. That mix shaped my skills and interests, and my hope for a PhD in the future.

News

  1. Released Video-HopChain: the paper, code, and the dataset and models.new

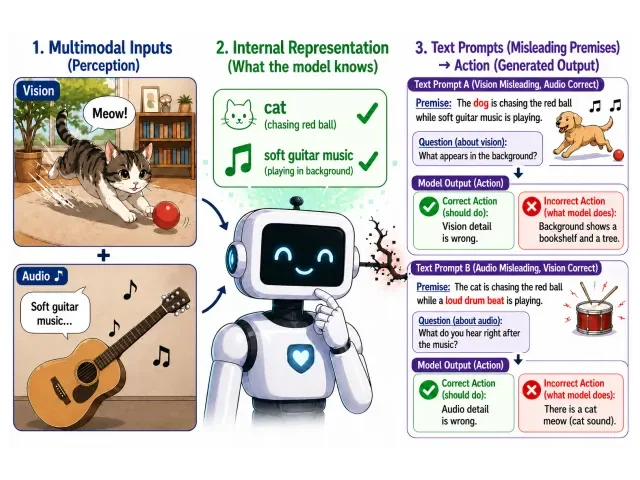
  2. Senses Wide Shut accepted to NeurIPS 2026, with the IMAVB benchmark and code released.

  3. Our code-switching DPO paper accepted to Interspeech 2026 as an oral presentation.

  4. Joined A*STAR as a research assistant on audio LLM post-training.

  5. AERO-1-Audio released.

  6. Joined S-Lab, NTU as an undergraduate research student.

Publications

Interspeech 2026 Oral First author

Direct Preference Optimization for English-Mandarin Code-Switching Speech Recognition in Audio LLMs

Trung Nguyen Quang, Cheng Yi Lewis Won, Minh Duc Pham, Yingxu He, Shuo Sun, Ai Ti Aw

DPO on 100K preference pairs (570 hours) teaches three Audio LLMs to transcribe mixed English–Mandarin speech instead of translating it, with MER reductions of up to 89.6%.

Experience

May 2025 — Present

Singapore

Research Assistant (Audio LLM Post-Training)

A*STAR — Agency for Science, Technology and Research

Advised by Dr. Sun Shuo

  • First author of a paper accepted to Interspeech 2026 as an oral presentation, targeting code-switching failures in Audio LLMs. Curated a dataset of 100K preference pairs (570 hours) and applied Direct Preference Optimization, resulting in MER reductions and behavioral improvement across MERaLiON Audio LLM, Phi-4-multimodal, and Qwen2-Audio.
  • Currently working on an audio reasoning project (ongoing).
  • Hands-on experience with post-training on large-scale servers, running jobs on up to 128 H100 GPUs.
Audio LLMsDPOAudio ReasoningLarge-Scale Training

Aug 2024 — Present

Singapore

Undergraduate Research Student

S-Lab for Advanced Intelligence, NTU

Advised by Prof. Ziwei Liu, Dr. Bo Li, Kaichen Zhang, Yuhao Dong

  • Led Video-HopChain: multi-hop video questions with one verifiable answer, and Confidence-Gated Exploration, a sampler that recovers zero-variance GRPO groups. Raised Qwen3-VL-8B from 52.3 to 59.3 mean accuracy on eight video benchmarks, and released the paper, code, dataset and models.
  • Led the development of a multimodal benchmark to diagnose the root causes of multimodal model failures by distinguishing between visual and audio errors, moving beyond isolated single-modality benchmarks to analyze capabilities in complex settings (accepted to NeurIPS 2026).
  • Contributed to the lmms-engine framework on GitHub (700 stars), integrating the Qwen Omni and Qwen VL series with advanced optimizations including Liger Kernel, sequence packing, DeepSpeed Ulysses sequence parallelism, and expert parallelism for efficient training.
  • Contributed to AERO-1-Audio, a small audio language model (1.5B params) achieving state-of-the-art performance on ASR and audio understanding benchmarks, demonstrating that smart data (50k hours) can outperform massive training approaches.
  • Contributed to the lmms-eval framework on GitHub (4.2k stars) by conducting research on Large Multimodal Models, including VLMs and ALMs, integrating new datasets and models, and optimizing the evaluation pipeline.
MultimodalOmni ModelsRLEvaluation

May 2024 — Aug 2024

Hanoi, Vietnam

Student Research Assistant (NLP)

Academy of Military Science and Technology

  • Developed and implemented a QCA (Question-Context-Answer) fine-tuning framework that extends beyond traditional QC pair fine-tuning for embedding models by simultaneously minimizing distances between all three semantic relationships (Question-Context, Question-Answer, and Answer-Context pairs), capturing deeper semantic understanding.
  • Achieved 10% MAP@K improvements over baseline QC fine-tuning in the legal document retrieval domain through QCA fine-tuning, testing on Vietnamese legal datasets with models including BAAI/bge-base-en-v1.5 and intfloat/multilingual-e5.
  • Extended QCA framework evaluation to general-domain retrieval tasks on the SQuAD dataset, with preliminary experiments showing promising generalization capabilities.
EmbeddingsRetrievalFine-tuning

May 2024 — Aug 2024

Hanoi, Vietnam

AI Engineer Intern

Vietnam Posts and Telecommunications Group

  • Built a Telegram chatbot for company customer support handling 100+ FAQ types using the LangChain framework, analyzing user queries to identify common failure patterns and redesigning prompts and the RAG pipeline accordingly.
  • Developed a RAG system for Vietnamese high school history exam prep using 10,000+ documents (textbooks, practice tests, QA pairs) by building an Elasticsearch index with custom document chunking, combining keyword search (BM25) with semantic search using embedding models, and integrating web search for topics not in the document base.
  • Tested the system on actual national graduation exams from 2019–2023; the baseline model scored 78% accuracy — after fine-tuning embeddings on history-specific data and optimizing the retrieval pipeline, achieved 88% accuracy (10% improvement).
RAGLangChainElasticsearch

Education

B.Eng in Electrical & Electronic Engineering

Nanyang Technological University, Singapore

2023 – 2027 (expected)

  • CGPA 4.96/5.0
  • Dean's List ×3
  • ASEAN Undergraduate Scholar
  • Projects Tech Lead (Main Committee) Machine Learning and Data Analytics Club @ NTU EEE

    Aug 2024 – May 2025

    Led the development of AI projects within the club's main committee.

Open Source Contributions

lmms-eval

4.2k Contributor

Unified evaluation framework for large multimodal models. Contributed model integrations, datasets, and pipeline improvements.

EvaluationVLMALM

lmms-engine

700 Contributor

Training engine for large multimodal models. Contributed model integrations and training optimizations (sequence packing, parallelism).

TrainingMultimodal

AERO-1-Audio

Contributor

A compact 1.5B audio language model with strong ASR and audio-understanding performance. Contributed to training and data work.

Audio LLMASR

tokless

280 Contributor

One CLI that installs and updates token-saving plugins (RTK, Caveman, CodeGraph, Context-Mode) for Claude Code, OpenCode and Codex. Contributed the headroom HTTP proxy lifecycle and agent routing.

Coding AgentsCLIGo