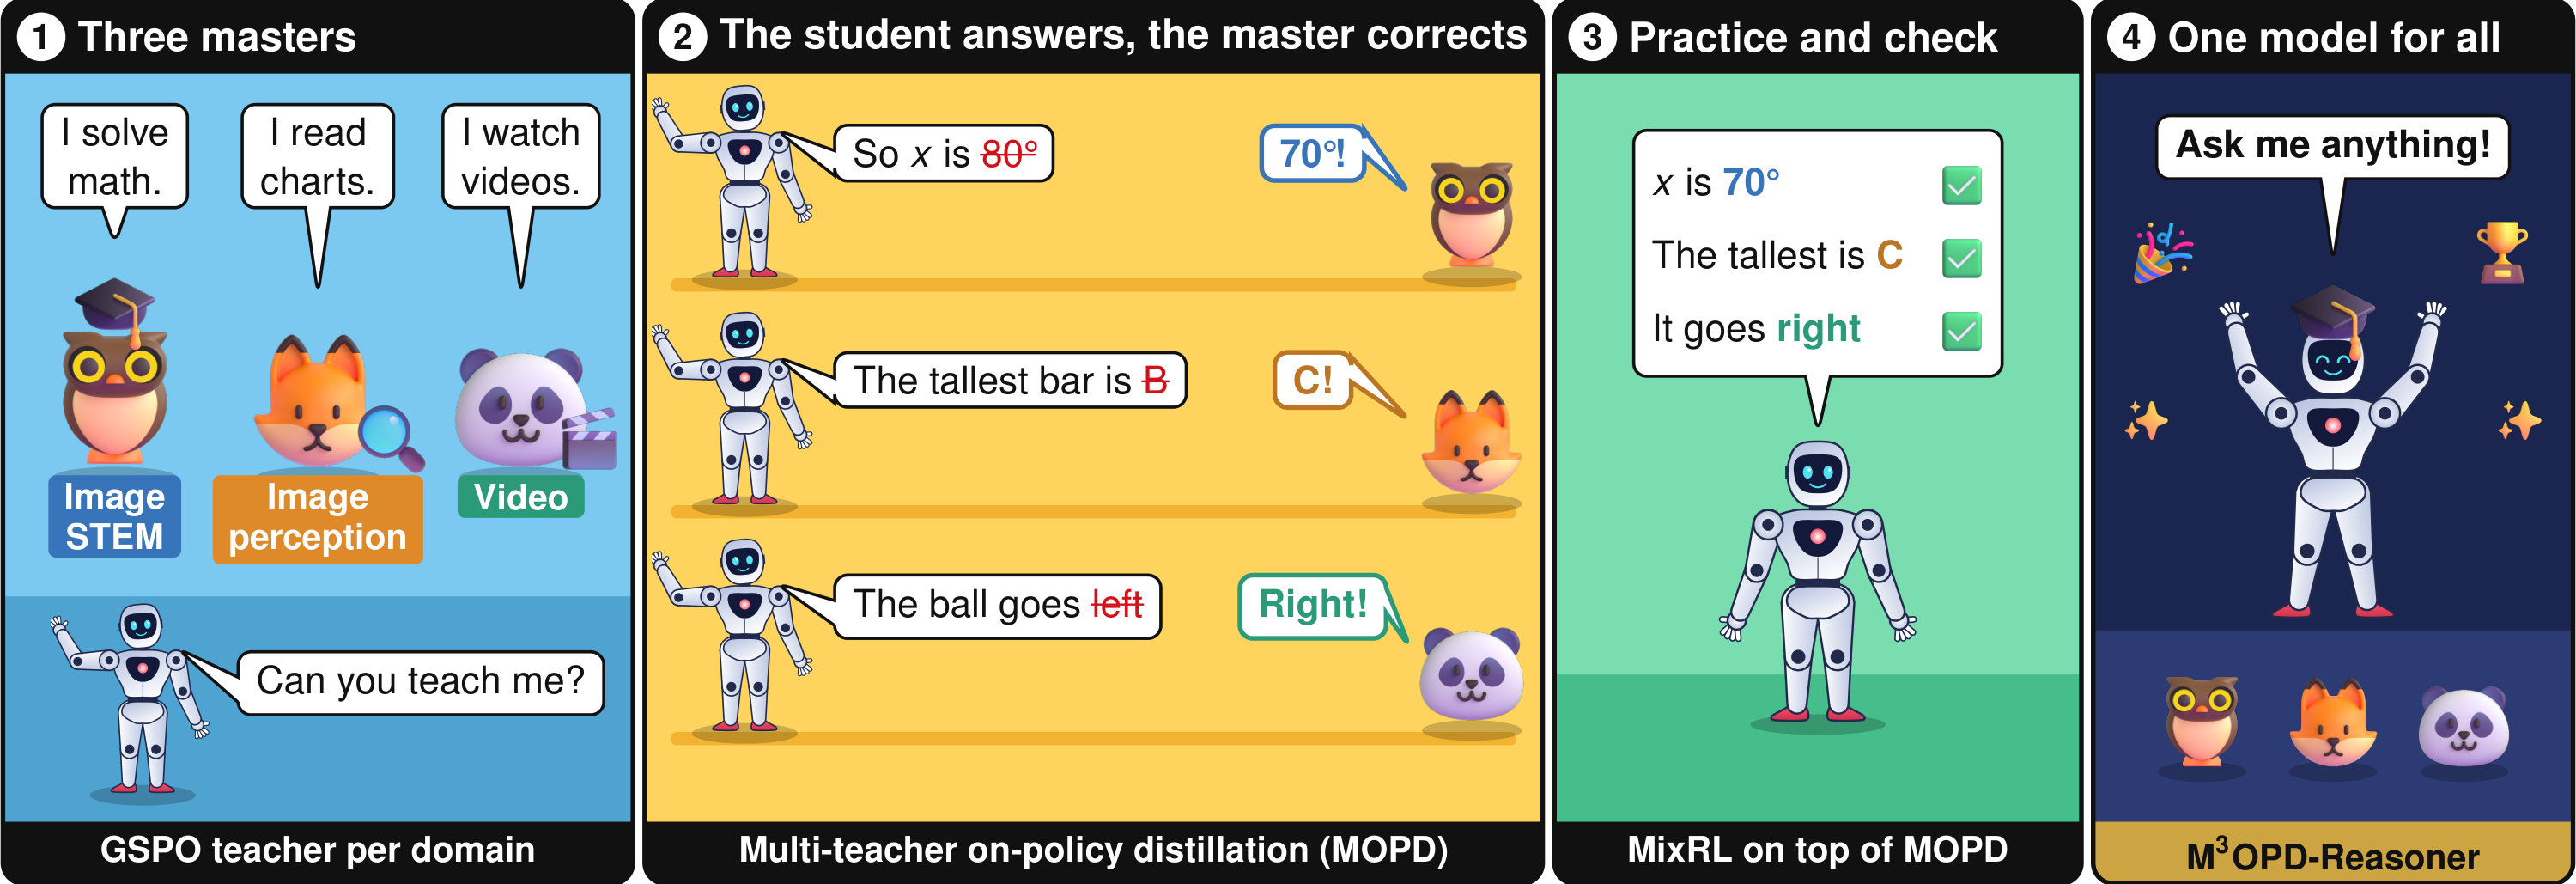
TL;DR. We train one teacher per domain (image STEM, image perception, video) with GSPO directly from Qwen3.5-9B, distill the three teachers into one student with multi-teacher on-policy distillation (MOPD), and then run MixRL on the same prompts on top of the MOPD student. The result is M³OPD-Reasoner-9B. The data, the training code and the checkpoints of every stage are online.
Overall
75.9
Qwen3.5-9B 69.4 · +6.5
Image STEM
77.1
Qwen3.5-9B 70.0 · +7.1
Image perception
81.9
Qwen3.5-9B 78.9 · +3.0
Video
64.1
Qwen3.5-9B 53.4 · +10.7
Mean accuracy (avg@8, %) of M³OPD-Reasoner-9B on 21 benchmarks, with the gain over Qwen3.5-9B.
Abstract
One recipe, three reasoning domains
Multi-Teacher On-Policy Distillation (MOPD) enables a single student to absorb the skills of several domain teachers by learning from its own generated responses. In this work, we present Multimodal Model Multi-Teacher On-Policy Distillation Reasoner (M³OPD-Reasoner), a fully open and complete recipe for post-training vision-language models (VLMs) over three reasoning domains: image STEM, image perception, and video. We first curate two datasets across the three domains, M³OPD-SFT-1.35M for supervised fine-tuning (SFT) and M³OPD-RL-193K for reinforcement learning (RL) with verifiable rewards.
On these data, we compare post-training recipes that start from Qwen3.5-9B: training one model on the mixed data of all domains (MixSFT and MixRL), and training one teacher per domain with Group Sequence Policy Optimization (GSPO), directly or after an SFT warm-up, and distilling the teachers into one student with MOPD. We evaluate on 21 image STEM, image perception, and video reasoning benchmarks after we decontaminate the training data against them. The comparison establishes MOPD of teachers trained with GSPO directly from Qwen3.5-9B as the best recipe: the student closely matches each teacher on its own domain and is on average above the mixed-training baselines on the same prompts.
Since MOPD already merges the domain capabilities that MixRL would otherwise have to learn, its student is a stronger starting point for RL, and we ask whether the same data can carry the model further from there: we add MixRL on top of the MOPD student, on the same prompts and with the same settings, which, to our knowledge, no prior VLM recipe has studied. The same prompts still improve the MOPD student, with no collapse, and give our main model, M³OPD-Reasoner-9B. MOPD and MixRL can therefore work as consecutive stages that get more out of the same data. To support reproducible research, we will release all data, the training code, and the checkpoints of every stage.
Recipe
Teachers, then one student, then RL on the same prompts
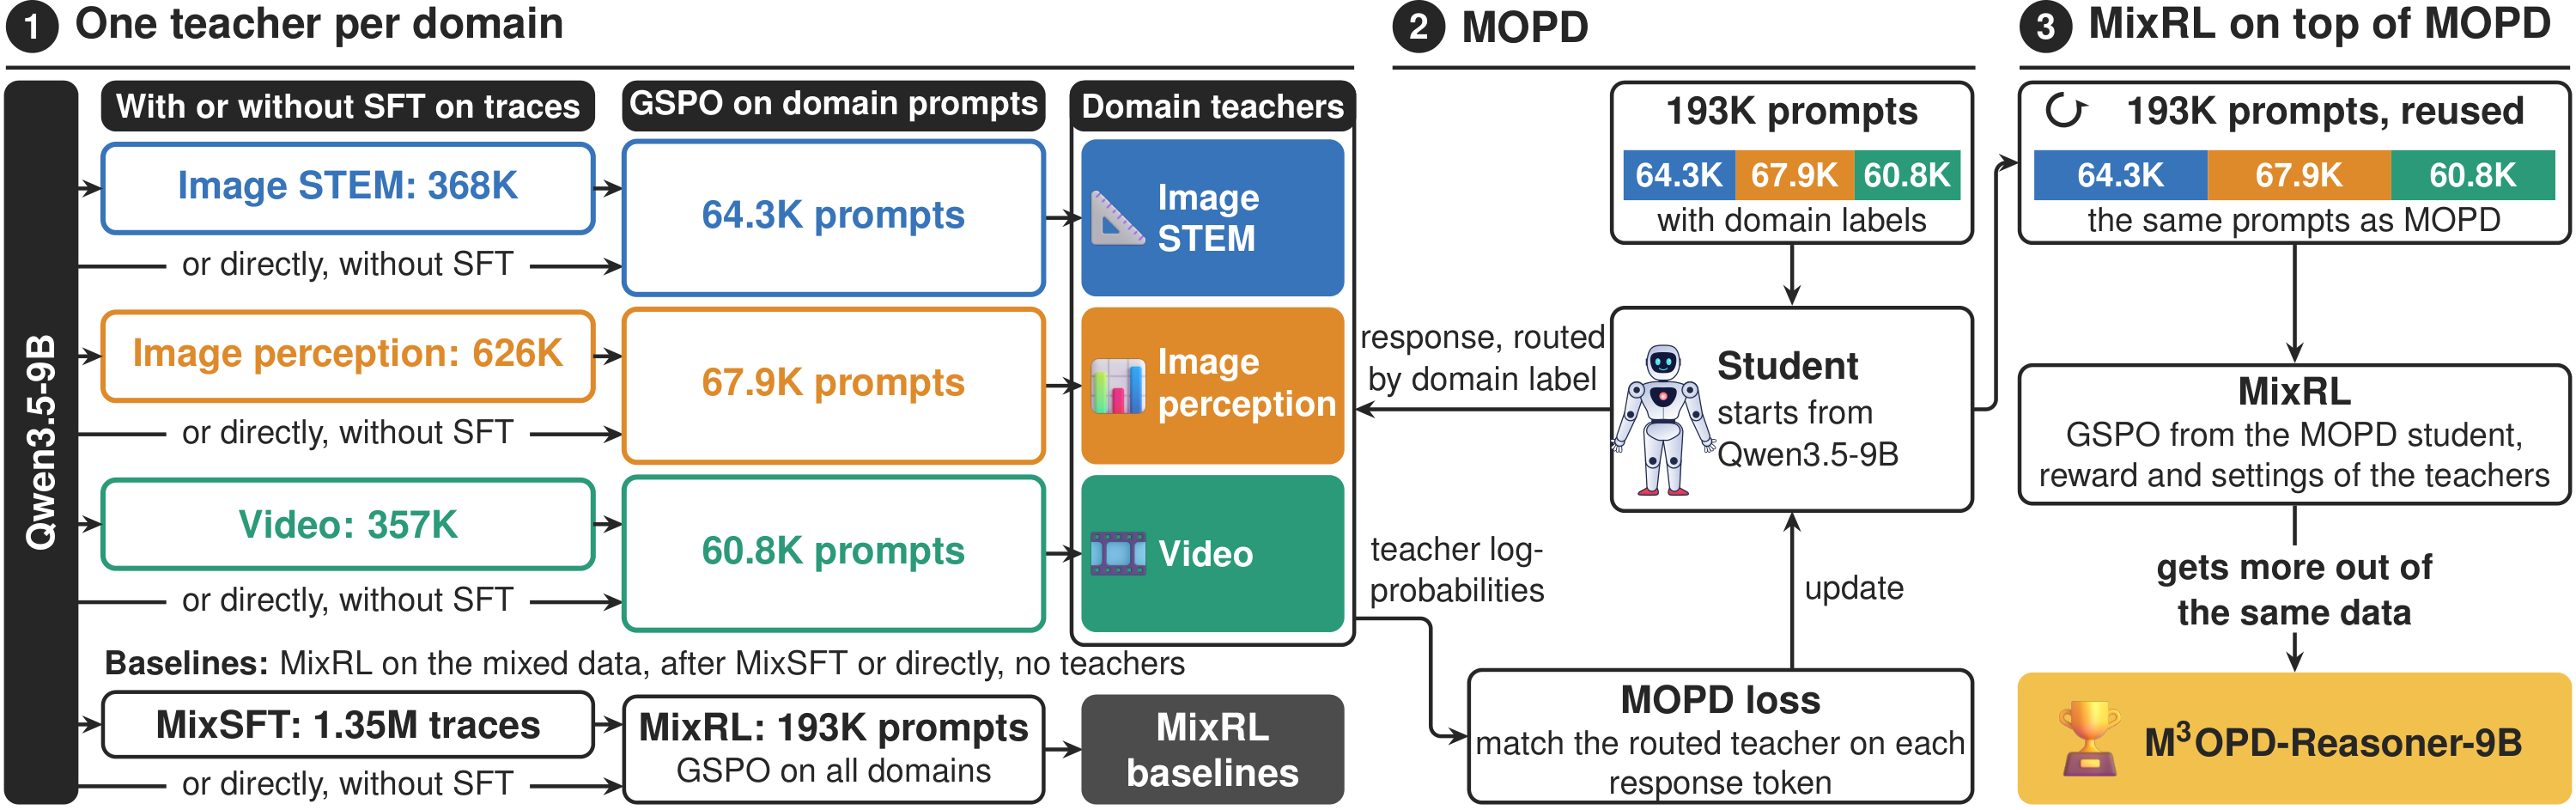
STAGE 1
One teacher per domain
GSPO on the prompts of one domain turns Qwen3.5-9B directly into the teacher of that domain. For comparison, we also train teachers after an SFT warm-up on the traces of the domain.
STAGE 2
MOPD
The student starts from Qwen3.5-9B and samples on the union of the RL prompts. The teacher of each prompt's domain scores every response token, and the student learns to match it.
STAGE 3
MixRL on top of MOPD
GSPO from the MOPD student on the same 193K prompts, with the reward and the GSPO settings of the teachers. This gives M³OPD-Reasoner-9B.
Data
Two open datasets
Both sets are decontaminated against the 21 evaluation benchmarks.
M³OPD-SFT-1.35M
Used by the MixSFT baseline and by the SFT warm-up of the compared recipe. Image STEM 368K and image perception 626K: self traces of Qwen3.5-9B, which receives the gold answer (78.1% of the generated image traces pass the filters). Video 357K: one Qwen3.8-Flash-Next trace per question.
Dataset on Hugging Face →M³OPD-RL-193K
Image STEM 64.3K, image perception 67.9K and video 60.8K prompts, each with a rule-verifiable answer. The same prompts serve the domain teachers, MOPD and MixRL.
Dataset on Hugging Face →Results
Stage by stage
| Model | Stages | Domain mean and overall mean, avg@8 (%) | ||||||
|---|---|---|---|---|---|---|---|---|
| SFT | Domain RL | MOPD | MixRL | Image STEM | Image perception | Video | Overall | |
| Qwen3.5-9B | 70.0 | 78.9 | 53.4 | 69.4 | ||||
| Mixed training on all domains | ||||||||
| MixRL | ✓ | 74.9 | 80.8 | 63.4 | 74.4 | |||
| MixSFT | ✓ | 63.4 | 77.7 | 58.8 | 67.7 | |||
| + MixRL (MixRL baseline) | ✓ | ✓ | 73.8 | 80.4 | 62.1 | 73.5 | ||
| Domain teachers with the SFT warm-up | ||||||||
| SFT warm-ups† | ✓ | 63.4 | 77.7 | 59.2 | 67.8 | |||
| + GSPO (domain teachers)† | ✓ | ✓ | 74.9 | 80.2 | 62.9 | 74.1 | ||
| + MOPD | ✓ | ✓ | ✓ | 74.8 | 80.6 | 62.8 | 74.2 | |
| + MixRL | ✓ | ✓ | ✓ | ✓ | 75.3 | 81.2 | 63.7 | 74.8 |
| Domain teachers without the SFT warm-up | ||||||||
| GSPO (domain teachers)† | ✓ | 76.7 | 81.2 | 63.4 | 75.2 | |||
| + MOPD | ✓ | ✓ | 76.6 | 81.4 | 63.2 | 75.2 | ||
| + MixRL (M³OPD-Reasoner-9B) | ✓ | ✓ | ✓ | 77.1 | 81.9 | 64.1 | 75.9 | |
Domain means and the mean of all 21 benchmarks (avg@8 accuracy, %). Check marks give the training stages of each row (Domain RL: GSPO on the prompts of one domain). †Three models, one per domain, each evaluated on its own domain. Bold: best in each column, without the † rows.
Comparison with reasoning VLMs
M³OPD-Reasoner-9B has the best result on 14 of the 21 compared benchmarks and the best or second-best result on 19 of them, with best results in all three domains. The other rows show published values, and a dash means that no comparable value is available.
| Image STEM | Image perception | |||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Model | Dyna | EMMA | Logic | Math | Math | MMMU | MMMU-Pro | We-Math | AI2D | Count | CV-Bench | Hallusion | MMStar | OCRBench | Real | Simple |
| OneThinker-8B | – | 10.9 | – | 64.3 | 77.6 | 70.6 | – | 54.6 | 85.2 | – | – | – | 70.6 | – | – | – |
| Video-HopChain-8B | – | – | – | – | – | – | – | – | 82.8 | – | – | – | 67.5 | – | 67.3 | – |
| OpenMMReasoner-7B | – | 24.5 | 51.9 | 63.7 | 79.3 | 57.6 | – | 53.8 | – | 81.9 | – | – | – | – | 68.8 | – |
| InternVL3.5-30B-A3B | – | – | 53.9 | 61.8 | 75.6 | 69.4 | – | 48.4 | – | 84.7 | – | – | – | – | 72.3 | – |
| MMFineReason-8B | – | – | 68.5 | 80.4 | 82.1 | 71.2 | – | – | – | 88.1 | – | – | – | – | 75.2 | – |
| MMVistaReason-9B | – | – | 68.5 | 82.4 | 83.6 | 73.6 | – | – | – | 92.8 | – | – | – | – | 77.4 | – |
| HopChain-35B-A3B | – | – | 75.6 | – | 85.0 | 78.3 | 70.6 | – | 91.3 | – | – | 66.5 | 78.6 | – | 79.4 | – |
| STEP3-VL-10B | – | – | 66.9 | – | 84.0 | 78.1 | 64.1 | 73.0 | 89.4 | 88.8 | 83.5 | 64.9 | 77.5 | 86.8 | 74.4 | 53.1 |
| MM-OPD-9B | 77.7 | – | 73.4 | – | 84.1 | 75.8 | 64.7 | 76.5 | – | – | – | – | 75.9 | 87.0 | 77.5 | 53.2 |
| M³OPD-Reasoner-9B | 80.0 | 57.5 | 79.6 | 84.6 | 87.1 | 76.0 | 69.7 | 82.5 | 92.1 | 98.4 | 89.1 | 78.9 | 79.3 | 90.0 | 78.6 | 49.1 |
| Video | |||||
|---|---|---|---|---|---|
| Model | Long | Temp | Video-Holmes | Video-MME | VSI-Bench |
| Video-R1-7B | – | 73.2 | 36.5 | 61.4 | 37.1 |
| Video-RTS-7B | 56.6 | – | 40.7 | 63.0 | – |
| Video-KTR-7B | – | 73.5 | 42.7 | 62.5 | – |
| Video-o3-7B | 60.5 | – | 46.5 | 66.5 | – |
| OneThinker-8B | 61.7 | – | 48.7 | 66.5 | – |
| Video-HopChain-8B | – | – | 48.6 | 69.2 | – |
| Video-MOPD-8B | – | 81.9 | 54.7 | 72.7 | – |
| Latent-OPD-9B | – | 70.6 | – | 66.5 | 54.9 |
| RLER-7B | 63.0 | 76.2 | – | 68.5 | 43.3 |
| M³OPD-Reasoner-9B | 63.3 | 76.2 | 53.1 | 70.0 | 58.0 |
Bold marks the best result and underline the second-best. The results of M³OPD-Reasoner-9B are avg@8. OpenMMReasoner, InternVL3.5 and MMFineReason use the values reported by MMVistaReason, and Video-R1 on Video-Holmes uses the value of the Video-Holmes paper. On EMMA and We-Math, OneThinker uses the values of Video-FLAIR and From Seeing to Thinking, OpenMMReasoner those of AnE and VeriEvol, and InternVL3.5 on We-Math its own.
Release
Data, code and checkpoints of every stage
We release all data, the training code and the checkpoints of every stage: the main recipe, the compared recipe with the SFT warm-up, and the baselines. The data, the code and the checkpoints are online now. Checkpoints that are online are in the M³OPD-Reasoner collection.
| Model | Repository | Recipe |
|---|---|---|
| Main recipe (no SFT warm-up) | ||
| M³OPD-Reasoner-9B (main model) | ngqtrung/M3OPD-Reasoner-9B | MixRL on top of the MOPD student |
| MOPD student | ngqtrung/M3OPD-MOPD-9B | MOPD of the three teachers, from Qwen3.5-9B |
| Image STEM teacher | ngqtrung/M3OPD-Teacher-ImageSTEM-9B | GSPO from Qwen3.5-9B |
| Image perception teacher | ngqtrung/M3OPD-Teacher-ImagePerception-9B | GSPO from Qwen3.5-9B |
| Video teacher | ngqtrung/M3OPD-Teacher-Video-9B | GSPO from Qwen3.5-9B |
| Compared recipe: with the SFT warm-up | ||
| Image STEM SFT warm-up | ngqtrung/M3OPD-Warmup-SFT-ImageSTEM-9B | SFT on the image STEM self traces |
| Image perception SFT warm-up | ngqtrung/M3OPD-Warmup-SFT-ImagePerception-9B | SFT on the image perception self traces |
| Video SFT warm-up | ngqtrung/M3OPD-Warmup-SFT-Video-9B | SFT on the Qwen3.8-Flash-Next video traces |
| Image STEM teacher with SFT warm-up | ngqtrung/M3OPD-Warmup-Teacher-ImageSTEM-9B | SFT warm-up + GSPO |
| Image perception teacher with SFT warm-up | ngqtrung/M3OPD-Warmup-Teacher-ImagePerception-9B | SFT warm-up + GSPO |
| Video teacher with SFT warm-up | ngqtrung/M3OPD-Warmup-Teacher-Video-9B | SFT warm-up + GSPO |
| MOPD student with SFT warm-up | ngqtrung/M3OPD-Warmup-MOPD-9B | MOPD of the SFT-warm-up teachers |
| MOPD + MixRL with SFT warm-up | ngqtrung/M3OPD-Warmup-MixRL-9B | MixRL on top of that student |
| Mixed-training baselines | ||
| MixSFT | ngqtrung/M3OPD-MixSFT-9B | SFT on the mixed traces of all domains |
| MixRL baseline | ngqtrung/M3OPD-MixRL-Baseline-9B | MixSFT + MixRL |
| MixRL from Qwen3.5-9B | ngqtrung/M3OPD-MixRL-From-Base-9B | MixRL directly from Qwen3.5-9B |
Data: M³OPD-SFT-1.35M and M³OPD-RL-193K. Code: M3OPD-Reasoner on GitHub.
Citation
BibTeX
@article{m3opdreasoner2026,
  title   = {M$^3$OPD-Reasoner: An Open Recipe for Post-Training Multimodal Reasoning
             with Multi-Teacher On-Policy Distillation},
  author  = {Nguyen Quang Trung and Hoang Phan and Shuo Sun and Longyin Zhang and AiTi Aw},
  journal = {arXiv preprint arXiv:2611.23034},
  year    = {2026}
}